Shui!
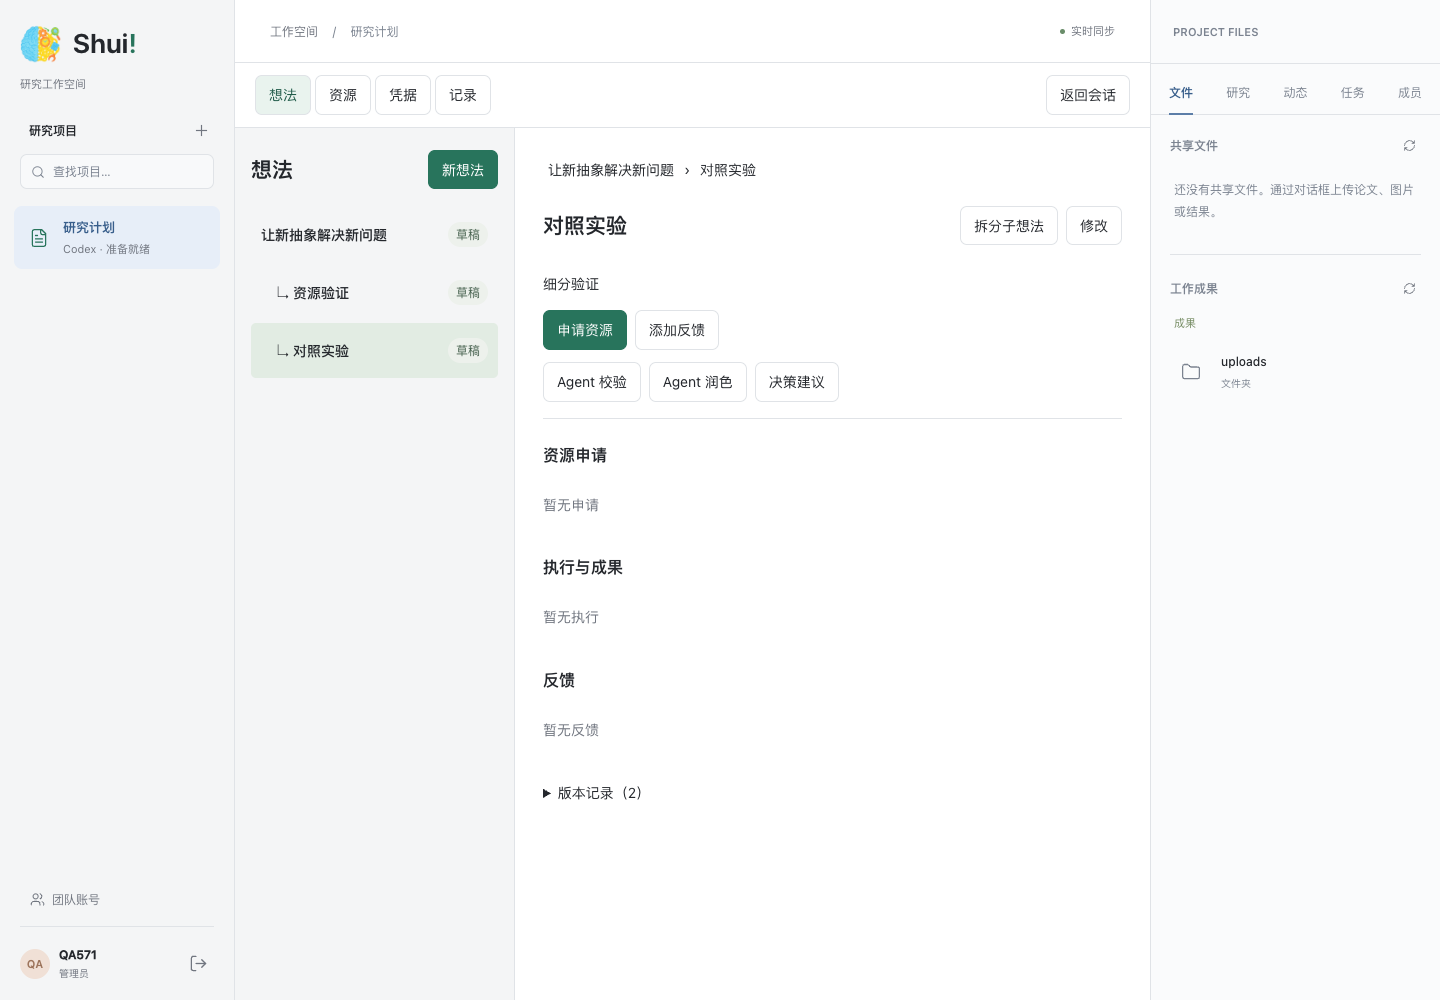
Develop connected ideas, request resources, share agent sessions, and keep feedback, experiments, and results in one workspace.
I am a Ph.D. student in Computer Science at Fudan University. I am fortunate to work with Yun Peng and Tao Xie. Previously, I received my M.S. in Computer Engineering from the University of California, Irvine, advised by Xiaohui Xie, and my B.Eng. from the Southern University of Science and Technology, advised by Yu Zhang.
I work on coding agents and multimodal reasoning. I am interested in personal agents that build and adapt software as people use it.
I believe the most exciting frontiers for AI are curiosity and abstraction.
“What magical trick makes us intelligent? The power of intelligence stems from our vast diversity, not from any single, perfect principle.”
— Marvin Minsky, The Society of Mind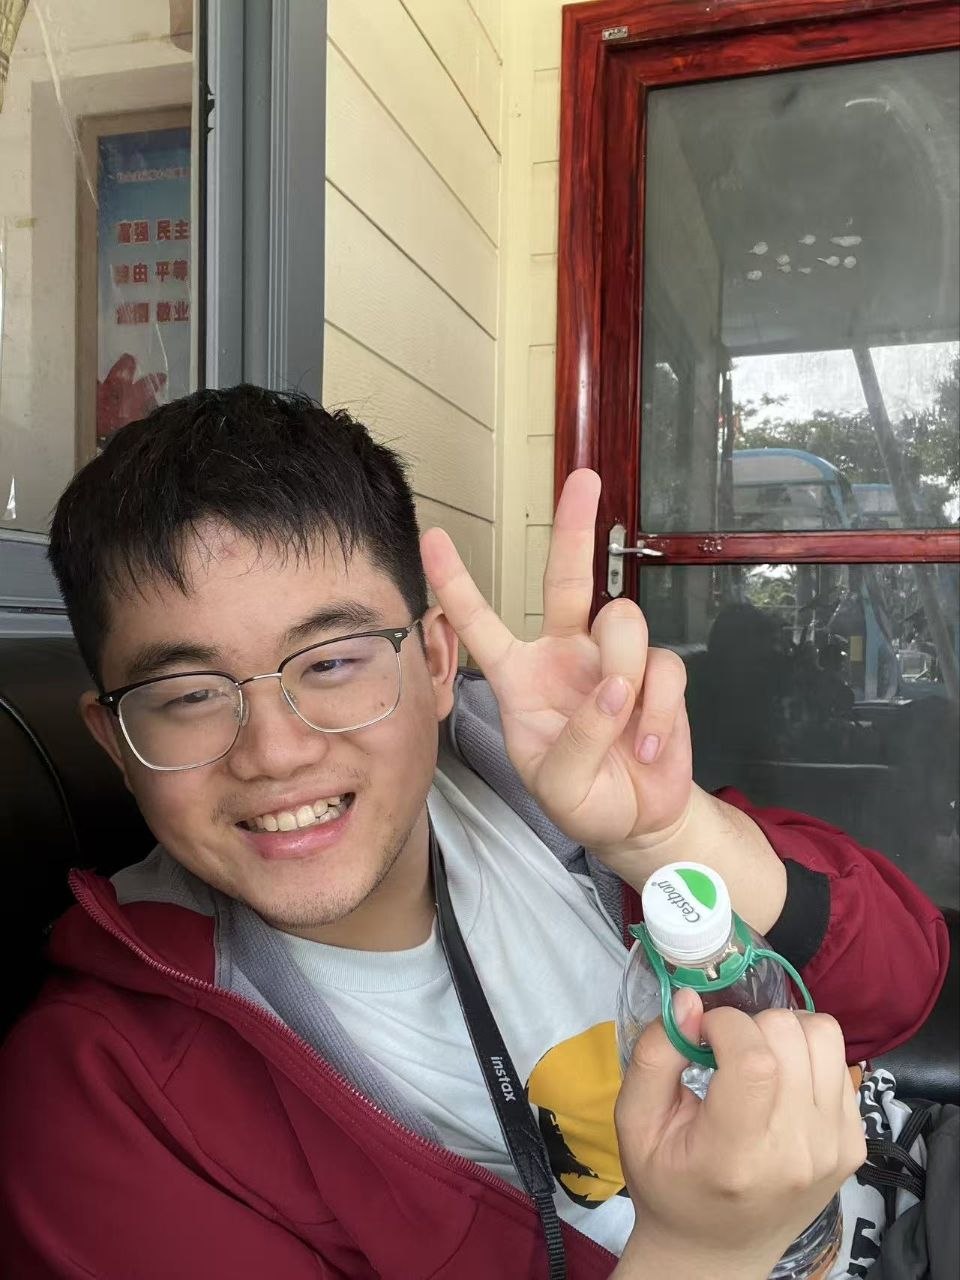
Develop connected ideas, request resources, share agent sessions, and keep feedback, experiments, and results in one workspace.

A voice-first embodied AI companion with simple physical expression, agent-to-agent chat, and a 3D-printable shell for desktop life.
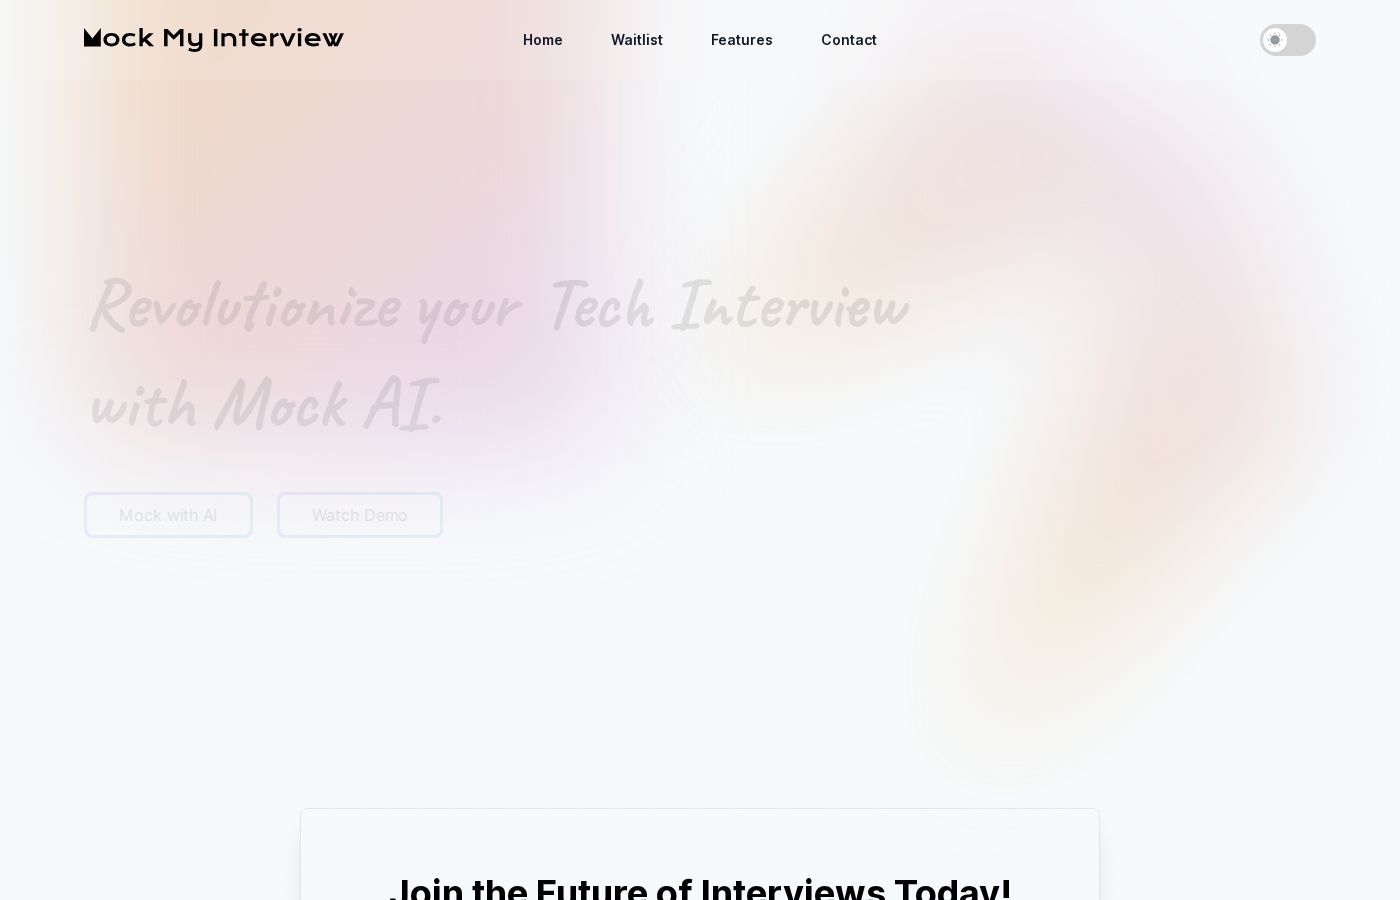
An AI-powered mock interview experience for practicing technical and behavioral interviews with interactive feedback.
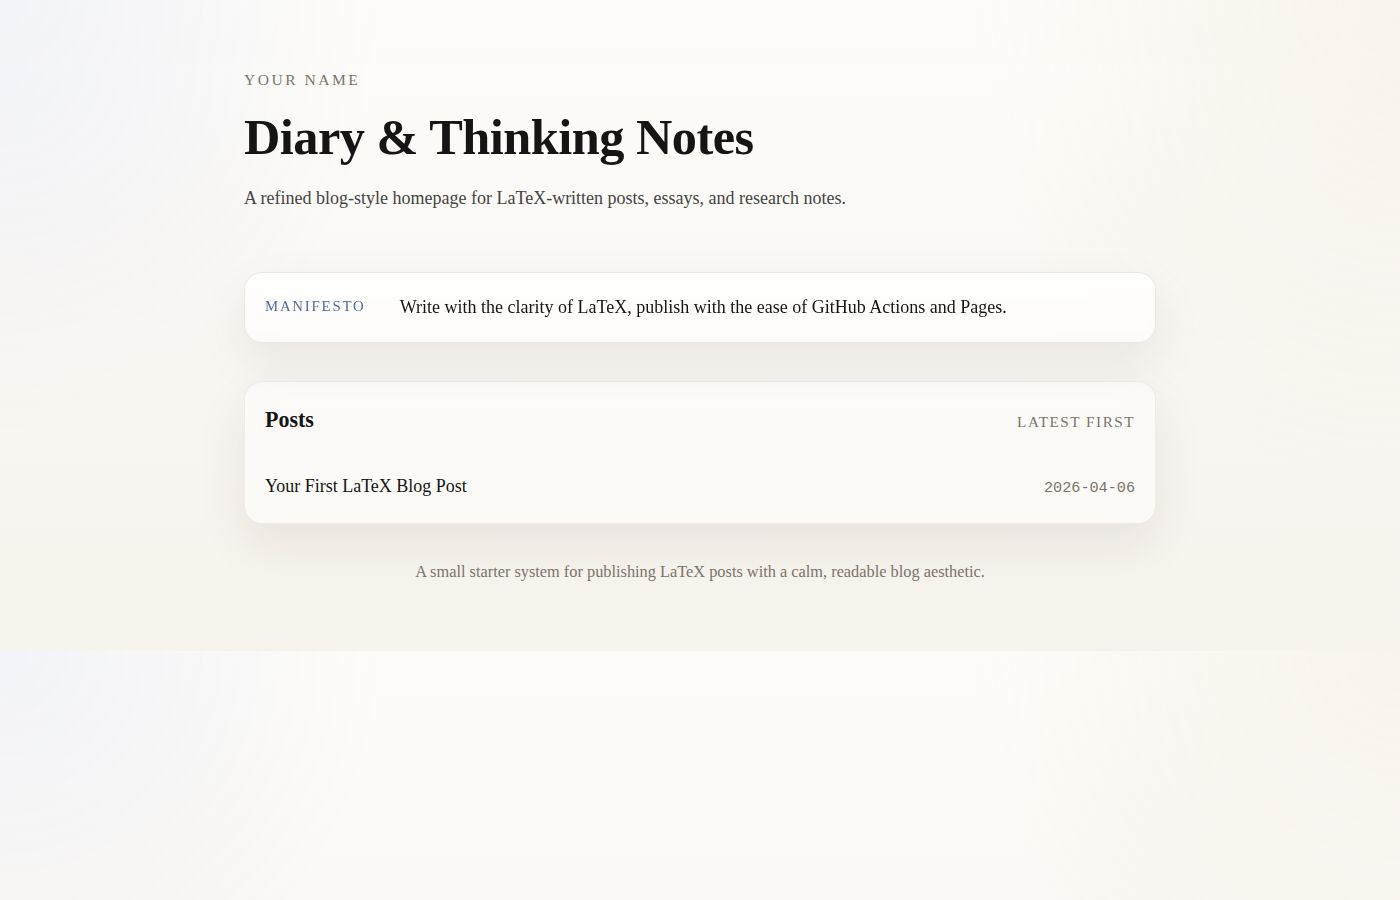
A reusable LaTeX blog system template with blog-style landing pages, automated compilation, and GitHub Pages deployment.


An app usually starts with a product team anticipating what people need. LiveUIBench asks what happens when an agent builds it for one person instead. It tests the resulting application through changing requests, real service actions, and return visits.

We track how correct outputs advance along a sequence as a transformer reuses the same block. The speed of this computation frontier connects training budgets to convergence and helps explain why a model that succeeds at one length can fail at another.
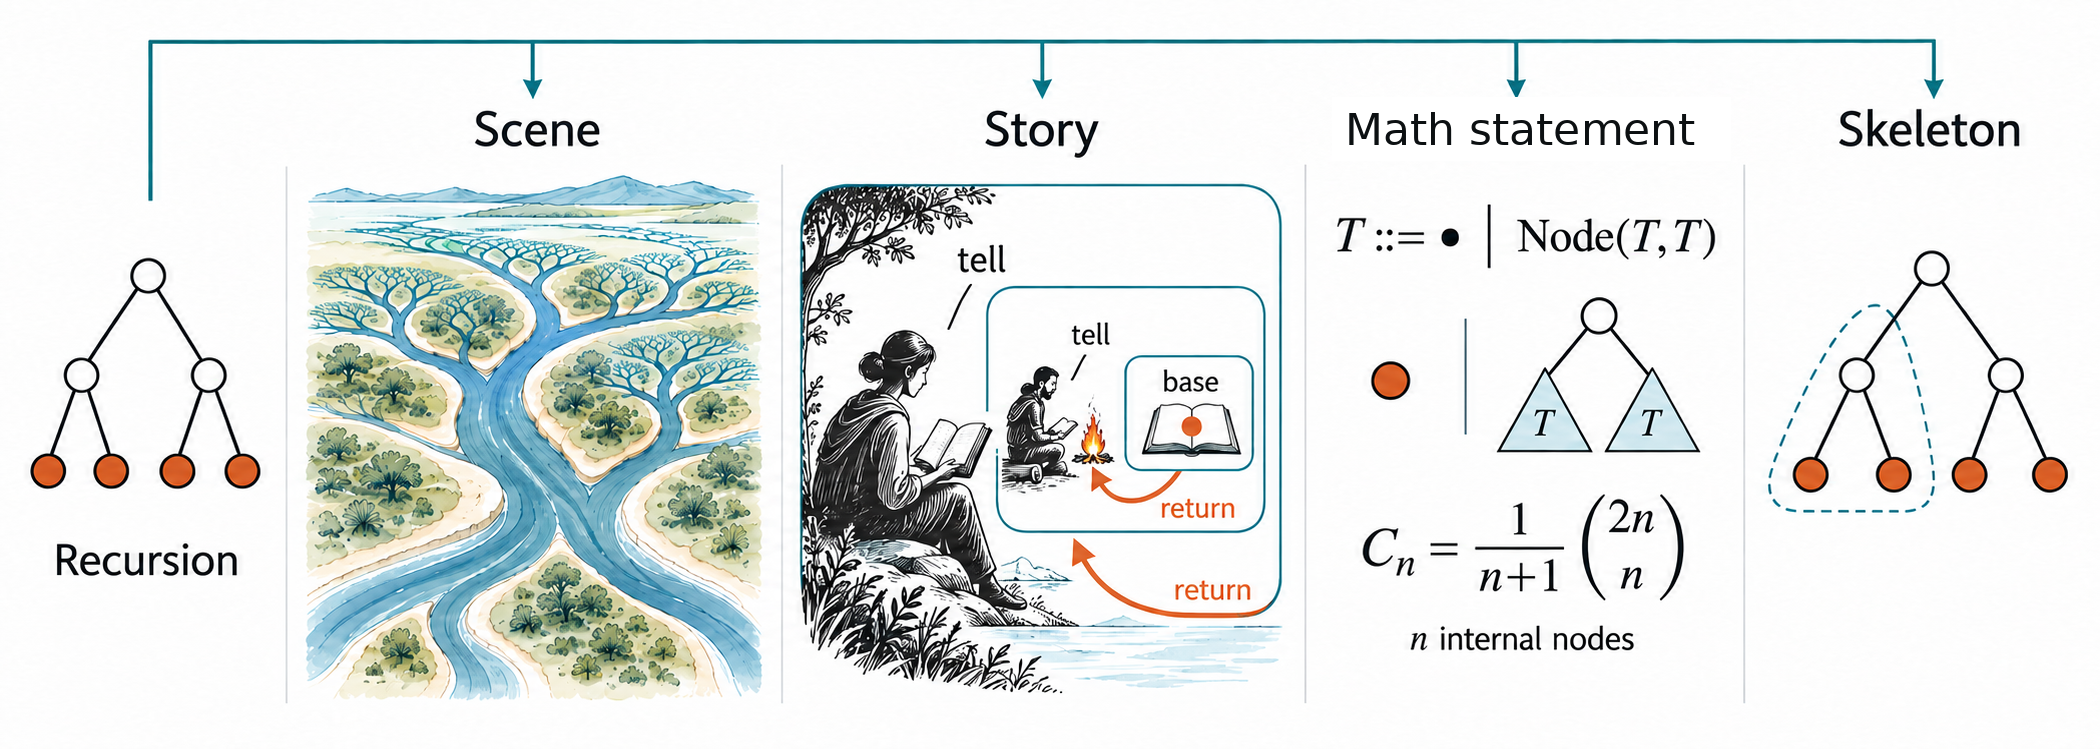
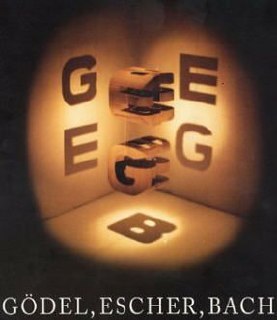
A picture can contain the same strange loop as a story. GEB-Bench tests whether models can recognize that shared structure across modalities. Recognizing the structure in each modality is much easier than matching it between image and text.
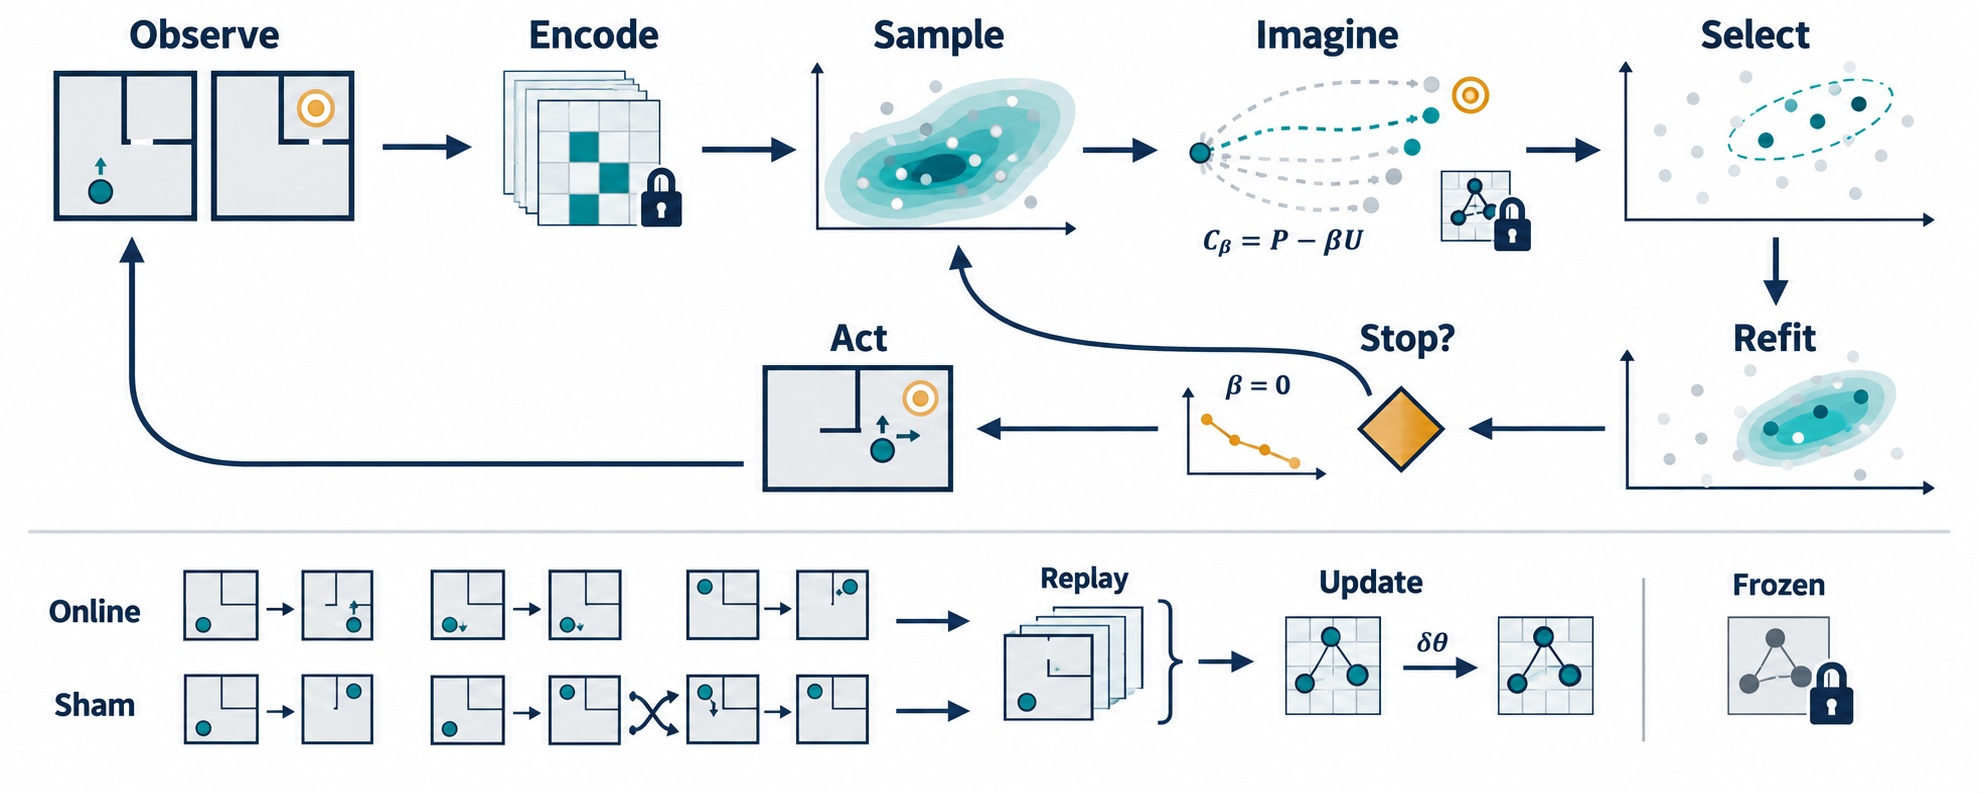
A planner can improve its internal score while choosing a worse action. We separate progress, disagreement, stopping, and world-model learning to find which parts of expected free energy help planning and when further computation should stop.
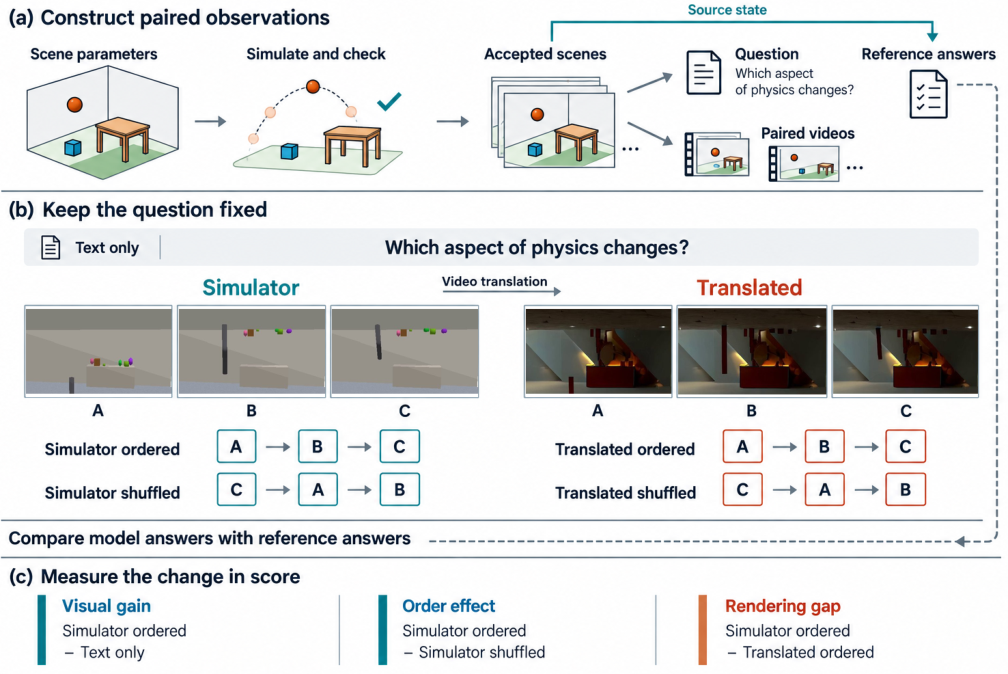
When a ball moves upward in a video, does a model follow the motion or answer from its knowledge of gravity? InfiniteWorld changes the simulated physics while keeping the questions comparable, exposing how familiar physical rules shape visual reasoning.

A jailbreak defense also changes how a model handles ordinary requests. We compare defenses through safety, task performance, over-refusal, and inference cost to show what each intervention changes beyond the attack it was designed to block.

The first study to adapt a pretrained autoregressive vision-language model for image-to-SVG code generation. Simple images become explicit shapes, colors, and spatial relationships that people can read and edit as code.
Tong Zhang, Yuxuan Cheng, Ruimin Zhang, Yun Peng, and Tao Xie†, “LiveUIBench: Evaluating Agent as App Workflows”, Preprint, 2026.
Tong Zhang, Junhao Hu, Yun Peng, and Tao Xie†, “When Does Recurrence Become an Algorithm? Convergence Selection in Weight-Tied Looped Transformers”, Preprint, 2026.
Tong Zhang, Zhiyuan Shi, Yun Peng, and Tao Xie†, “GEB-Bench: Abstract Structures Told in Many Voices”, Preprint, 2026.
Tong Zhang, Zhiyuan Shi, Yun Peng, and Tao Xie†, “Knowing When to Stop Thinking: A Dissection of Expected Free Energy as a Test-Time Compute Controller for Latent World-Model Planning”, Preprint, 2026.
Tong Zhang, Yuxuan Cheng, and Yun Peng†, “InfiniteWorld: Separating Visual Evidence from Familiar Physics”, Preprint, 2026.
Tong Zhang, Zexin Li, Simin Chen, and Yun Peng†, “When LLM Defenses Backfire: Characterizing Safety, Performance, and Cost Trade-offs”, Preprint, 2026.
Tong Zhang, Haoyang Liu, Peiyan Zhang, Yuxuan Cheng, and Haohan Wang, “Beyond Pixels: Exploring Human-Readable SVG Generation for Simple Images with Vision Language Models”, Preprint, 2023.
Zebin Yun, Shengjie Niu, Tong Zhang, and Jian Huang, “Proof of Forgeability: Challenging the Evidentiary Reliability of Membership Inference”, Under Review, SaTML 2027.
Sinin Zhang, Yunfei Xie, Yuxuan Cheng, Haoyu Zhang, and Tong Zhang, “PhysNote: Self-Knowledge Notes for Evolvable Physical Reasoning in Vision-Language Model”, ES-Reasoning @ ICLR, 2026.
Haoyu Ma, Tong Zhang, Shanlin Sun, Xiangyi Yan, Kun Han, and Xiaohui Xie, “CVTHead: One-shot Controllable Head Avatar with Vertex-feature Transformer”, IEEE/CVF Winter Conference on Applications of Computer Vision (WACV), 2024.
Bu Jin, Xinyu Liu, Yupeng Zheng, Pengfei Li, Hao Zhao, Tong Zhang, Yuhang Zheng, Guyue Zhou, and Jingjing Liu, “ADAPT: Action-aware Driving Caption Transformer”, IEEE International Conference on Robotics and Automation (ICRA), 2023.
Sep. 2025 – Dec. 2025
Developed a WeChat Mini Program agent based on vision-language models, and designed agent memory together with experience extraction mechanisms.
May 2025 – Aug. 2025
Proposed an energy-based attention refinement method for image editing, and explored generate–reflect–reason loops for multi-round controllable optimization.
Nov. 2024 – Apr. 2025
Studied defense mechanisms for large language models, their side effects, and token compression for audio language models.
May 2022 – Sep. 2022
Implemented PP-OCRv2 detection in OpenCV Zoo, high-level C++ APIs, and evaluation metrics for text detection.
I believe in drinking plenty of water and getting plenty of sleep. Hoping to build a lean physique someday.
Tong’s assistant for his work, papers, and meeting requests.
This conversation is stored to keep its context. Meeting details are shared with Tong. Rock uses public information and cannot confirm Tong’s availability.